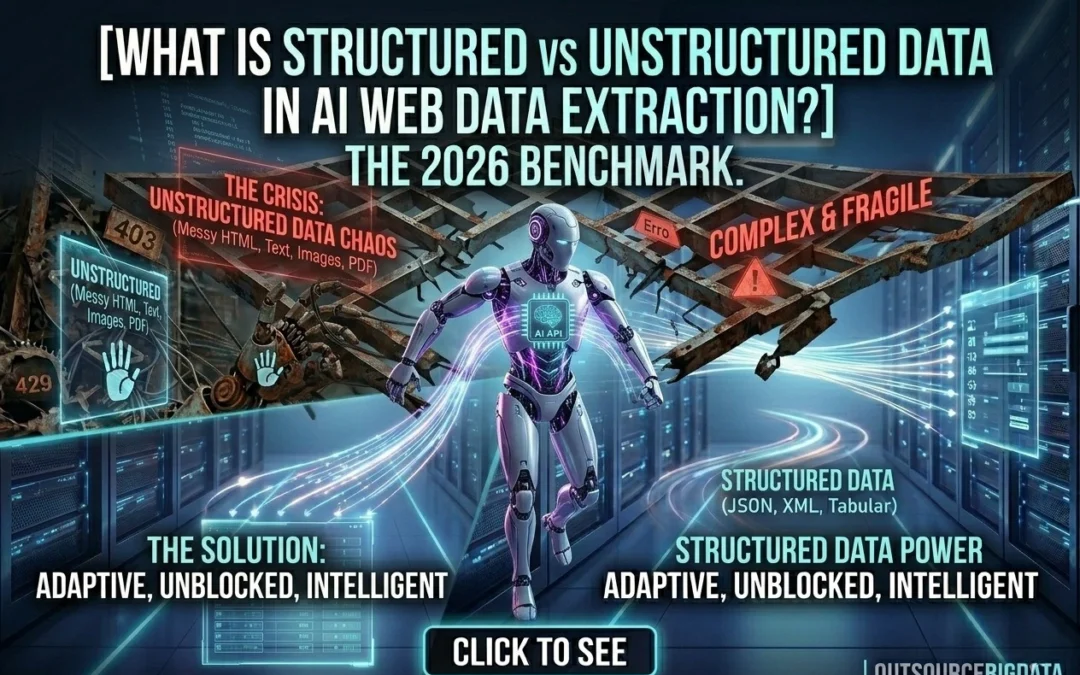
What is Structured vs Unstructured Data in AI Data Extraction? | Outsourcebigdata
Author : Jyothish
What is Structured vs Unstructured Data in AI Data Extraction? | Outsourcebigdata
Author : Jyothish
AIMLEAP Automation Works Startups | Digital | Innovation | Transformation
Table of Contents
- What is Structured vs Unstructured Data in AI Data Extraction?
- Why the Type of Data You Extract Actually Matters
- What is Structured Data, and What Does It Look Like on the?
- What is Unstructured Data, and Why is Most of the Built This Way?
- What is Semi-Structured Data, and Where Does HTML Actually Fit?
- How Do You Convert Raw HTML Into Clean Structured Data?
- How Does AI Extraction Work Differently From a Traditional Parser?
- What Tools Are Being Used for AI Extraction Right Now?
- Structured vs Unstructured vs Semi-Structured: Side-by-Side
- What This Looks Like in Real Projects
- Common Mistakes When Extracting Unstructured Data
- Frequently Asked Questions
What is Structured vs Unstructured Data in AI Data Extraction?
- Structured data has a fixed format (rows, columns, JSON fields) and is ready to use the moment you receive it.
- Unstructured data has no fixed format — raw HTML, review text, blog articles, and PDFs all count.
- Semi-structured data (HTML, XML, JSON) sits in between: it has tags but no guaranteed schema.
- AI extractors now convert unstructured pages into clean structured outputs using plain English, without breaking when a site redesigns.
If you have ever tried to pull product prices from a website and ended up with a wall of HTML tags instead of a clean spreadsheet column, you already know this problem firsthand. The gap between structured and unstructured data is the single biggest reason data projects either run smoothly or turn into maintenance nightmares.
In 2026, with AI extraction tools reshaping how businesses collect data, understanding this distinction has become more important than ever. At Outsourcebigdata, we work with data teams who wrestle with exactly this challenge every week. This guide gives you a clear, practical answer with no unnecessary complexity.
Why the Type of Data You Extract Actually Matters
Here is a number worth knowing before anything else: approximately 80 to 90 percent of all data generated globally is unstructured, according to IDC. Only about 20 percent sits in neat, queryable formats. On the, that imbalance is even more pronounced. Most pages are designed for human readers, not machines. That means the moment you start extracting data, you are almost always starting with unstructured content.
This matters because the tools, time, and cost required are fundamentally different depending on which format you are working with:
- Structured data goes directly into a database, dashboard, or model with no extra work.
- Unstructured data needs cleaning, parsing, and mapping before it becomes usable.
- Choosing the wrong approach is the number one reason scrapers break and data projects go over budget.
What is Structured Data, and What Does It Look Like on the?
Structured data is information organized into a fixed schema. Every record follows the same format, every field has a defined data type, and you can query the whole thing with a standard tool like SQL. Think of it as a spreadsheet where every row and column means exactly one thing.
On the, you find true structured data in a few predictable places:
- REST API responses (product name, price, stock status delivered as a clean JSON object)
- Pre-built data endpoints from scraping platforms such as structured SERP APIs
- Sitemap XML files with consistent, repeating fields
- CSV or database exports from e-commerce backends
Here is what clean structured output looks like in practice:
{“product_name”: “Running Shoes X200”, “price”: 89.99, “rating”: 4.6,
“in_stock”: true }
Every field is labeled. Every value is consistent. You can feed this directly into your analysis pipeline without touching it again. The main advantages are no preprocessing, lower infrastructure cost, higher data quality, and direct compatibility with BI and machine learning tools. The catch is that structured data is genuinely rare. Most websites do not expose a clean API, and when they do, rate limits or authentication often get in the way.
What is Unstructured Data, and Why is Most of the Built This Way?
Unstructured data has no predefined format. There is no consistent schema, no labeled fields, and no guarantee that two pages from the same website will organize their content the same way. The is built this way because humans wrote it for humans, using whatever CMS, template, or custom code made sense at the time.
Common examples of unstructured data include:
- Raw HTML pages (the most common form a scraper receives)
- Product review paragraphs and user comments
- Blog articles and news stories
- Job description text embedded in career pages
- Social media posts and Reddit threads
- PDFs and scanned documents linked from pagesWhen you scrape an unstructured page, you receive the entire HTML document: navigation menus, ad slots, footer links, cookie banners, and somewhere in the middle, the content you actually wanted. Separating signal from noise requires additional processing, and that processing breaks every time the site changes.
Why Does Unstructured Data Break Traditional Scrapers So Often?
The most common issue is CSS selector brittleness. You write a selector to find a price inside a specific div. It works perfectly. Three weeks later, the site redesigns their product page and that div no longer exists. Other problems that compound this include:
- JavaScript-rendered content that a basic HTML parser never loads
- Inconsistent markup across different pages of the same site
- Content hidden behind pagination, login walls, or lazy loading
- Encoding issues in international character sets
What is Semi-Structured Data, and Where Does HTML Actually Fit?
Most articles about this topic present it as a simple binary: structured or unstructured. That is incomplete. There is a third category that covers most of what you encounter when scraping: semi-structured data.
Semi-structured data has some organizational markers (tags, key-value pairs, hierarchies) but does not enforce a rigid schema. HTML, XML, and JSON all sit in this middle ground. HTML is the clearest example. It uses defined tags like <h1>, <p>, and <div>, which gives it some structure. But there is no rule about what goes inside those tags, how deeply they can be nested, or whether a price will appear inside a semantically meaningful element or an arbitrary div with a random class name.
Where each format sits:
- HTML: structured tags, unstructured content within them
- JSON: key-value structure, but fields vary between records
- XML: hierarchical and tagged, but schema is optional
- Email: structured metadata (sender, timestamp), unstructured body text
The email example matters:
An email has a structured envelope (sender address, timestamp, subject line) that you can query like a database field. But the message body is free text with no schema at all. AI agents need to handle both layers at once: querying the metadata and reading the body with natural language understanding. This is exactly the pattern you encounter on complex pages.
Understanding semi-structured data matters because most modern extraction workflows involve converting semi-structured HTML into fully structured JSON or CSV. The transformation gap between these two states is where the majority of complexity and cost lives in any data pipeline.
How Do You Convert Raw HTML Into Clean Structured Data?
The traditional approach follows three steps:
- Fetch the raw HTML using a request library (Python’s requests module, for example)
- Parse the HTML tree and extract content using CSS selectors or XPath expressions
- Map the extracted content into a structured schema (JSON, CSV, or a database row)
A simple Python example using BeautifulSoup:
import requests
from bs4 import BeautifulSoup
url = “https://example.com/product“
soup = BeautifulSoup(requests.get(url).text, “html.parser”)
product = {
“name”: soup.select_one(“.product-title”).text.strip(),
“price”: soup.select_one(“.price”).text.strip(),
“rating”: soup.select_one(“.rating-value”).text.strip()
}
This works well for simple, static pages with consistent HTML. The problems start when the site changes its layout, when content loads via JavaScript, or when you are scraping dozens of different sites each with unique markup. Each new site requires custom logic. Every redesign triggers a maintenance cycle. At Outsourcebigdata, we regularly take on data collection projects where the client’s previous approach was a collection of fragile selectors that someone had to manually update after every site change.
How Does AI Extraction Work Differently From a Traditional Parser?
AI-powered extraction replaces brittle selectors with semantic understanding. Instead of telling a scraper exactly where to find a price in the HTML tree, you describe what you want in plain English and the model finds it based on meaning, not position.
Compare the two approaches:
- Traditional parser: Find the text inside the element with class ‘product-price’ inside a div with id ‘main-content’.
- AI extractor: Extract the product name, price, and customer rating.
The AI reads the page the way a human would. It understands that a dollar figure near the word ‘price’ or ‘cost’ is almost certainly what you want, regardless of which HTML element happens to contain it. A 2026 benchmark study found that LLM-powered scrapers required 70 percent less maintenance than selector-based scrapers when websites changed their design. For teams managing large-scale data collection, that translates directly to engineering hours and project cost.
The practical benefits of AI extraction over traditional parsing:
- Extraction survives site redesigns since the AI looks for meaning rather than HTML structure
- Works across different sites with one prompt instead of custom logic per domain
- Handles context-dependent data, such as distinguishing a sale price from a regular price
- Generates consistent JSON output regardless of the underlying HTML variation
At Outsourcebigdata, this shift from selector-based to AI-native extraction has changed how we scope data collection projects for clients. What previously required weeks of custom scraper development now takes a fraction of the time, and the pipelines stay stable for far longer before needing attention.
What Tools Are Being Used for AI Extraction Right Now?
Several tools are leading this space in 2026. Firecrawl accepts a URL and returns LLM-ready structured output with a single API call. ScrapeGraphAI lets you use natural language prompts to describe what you want and delivers structured JSON, with support for multiple LLM providers. Diffbot uses computer vision and NLP to identify and extract data from pages without relying on DOM structure at all. Each takes a slightly different approach, but all three remove the need to write or maintain CSS selectors.
Structured vs Unstructured vs Semi-Structured: Side-by-Side
| Feature | Structured | Semi-Structured | Unstructured |
| Schema | Fixed and defined | Flexible / partial | None |
| Preprocessing | None required | Minimal | Significant |
| Storage | SQL databases, CSV | NoSQL, JSON stores | Data lakes, raw files |
| examples | API responses, data feeds | HTML, XML, JSON pages | Review text, PDFs, images |
| AI readiness | Direct use | Moderate effort | Requires NLP or vision |
| Extraction complexity | Low | Medium | High |
What This Looks Like in Real Projects
E-commerce price monitoring
A retail team needs daily price data from 200 competitor product pages. The pages are unstructured HTML. Using an AI extractor with a schema prompt (extract product name, current price, original price, discount percentage), they receive clean JSON for every page. When one competitor redesigns their product page, the extraction continues without interruption. No selector updates are needed.
Competitor review analysis
A SaaS company wants to analyze customer sentiment from review sites. Review text is entirely unstructured. An NLP pipeline extracts key themes, sentiment scores, and feature mentions from raw review paragraphs and maps them to a structured dataset. The input was unstructured. The output is a clean structured table ready for analysis.
Job listings aggregator
A recruitment platform scrapes job postings from 50 different company career pages. Each page uses different HTML. Using AI extraction with a consistent schema (job title, location, salary range, required skills), the platform receives uniform structured data regardless of how each source page is marked up.
Common Mistakes When Extracting Unstructured Data
Based on what the Outsourcebigdata team encounters most often in client projects, these are the patterns that cause the most problems:
- Assuming page consistency: Not every product page on a site uses the same template. Pages added at different times often have different structures even within the same domain.
- Ignoring JavaScript-rendered content: If your parser fetches raw HTML without executing JavaScript, dynamic content will simply not be present. Use a headless browser or an extraction API that handles rendering.
- Storing raw HTML instead of extracting first: Raw HTML bloats storage, is difficult to query, and loses relevance every time the source site changes its layout.
- Over-engineering when an API exists: Before writing a scraper, check whether the target site has a public API or a pre-built structured data feed. Using one saves significant development time.
- Not validating AI-extracted output: AI extractors can miss fields on complex or unusual pages. Always validate the schema of your output, especially for critical data like prices or dates.
FAQs
Questions sourced from Reddit communities and Google’s People Also Ask for the search intent ‘how does AI data extraction work?’
How does AI actually know what to extract from an unstructured page?
AI models trained on large text datasets develop an understanding of semantics and context. When given a prompt like ‘extract the product price,’ the model identifies text that contextually represents a price based on surrounding language cues rather than HTML structure. This is why AI extraction stays accurate even after a site redesigns its layout.
Is scraping legal in 2026?
This depends on the site’s terms of service, the data being collected, and your jurisdiction. Publicly available data scraped without bypassing access controls is generally permissible in many regions, but always review the target site’s robots.txt and terms before collecting data at scale. Outsourcebigdata recommends reviewing legal guidance for any commercial data collection project.
What is the difference between a scraper and an AI extractor?
A web scraper fetches HTML and extracts content using rules such as CSS selectors or XPath. An AI extractor processes the page semantically and returns structured output based on what you described in plain language. The AI approach is more flexible and far less brittle, though it may be slower or more costly at very high volume.
Why does my scraper keep breaking every few weeks?
Almost certainly because you are using CSS selectors on a site that updates its design or HTML structure regularly. The selector points to a specific element that no longer exists after the redesign. Switching to a schema-based AI extractor or using a structured data endpoint removes this dependency entirely.
Can AI extract data from PDFs and images, not just pages?
Yes. AI extraction using OCR and vision models can process scanned documents, PDF invoices, and images to return structured data. The same semantic understanding that works on HTML applies to these formats. Services like Diffbot and Mindee specialize in document extraction alongside web page extraction.
What is the best way to store structured data after extraction?
Relational databases (PostgreSQL, MySQL) work well for structured output with a consistent schema. If your schema evolves or varies across sources, a document store like MongoDB handles semi-structured JSON output better. The key is not storing raw HTML as your primary data store, which makes querying and maintenance significantly harder.
Get Notified !
Receive email each time we publish something new: